

HYBRID MIND · AGENT ENGINEERING · TOOL CALLING / API
API ตอบ 200 แต่ Agent อ่านครบหรือยัง? ออกแบบ Pagination ให้รายงานข้อมูลที่ยังขาด
Agent เรียก API สำเร็จ อ่านรายการ แล้วบอกว่า “ตรวจครบแล้ว” ทั้งที่ยังมีหน้าถัดไป ความผิดพลาดนี้เกิดได้แม้ JSON ถูกต้อง เพราะความสำเร็จของคำขอหนึ่งครั้งกับความครบถ้วนของชุดข้อมูลเป็นคนละเรื่อง
Quick Answer: ให้เครื่องมือรายงานขอบเขตที่อ่าน
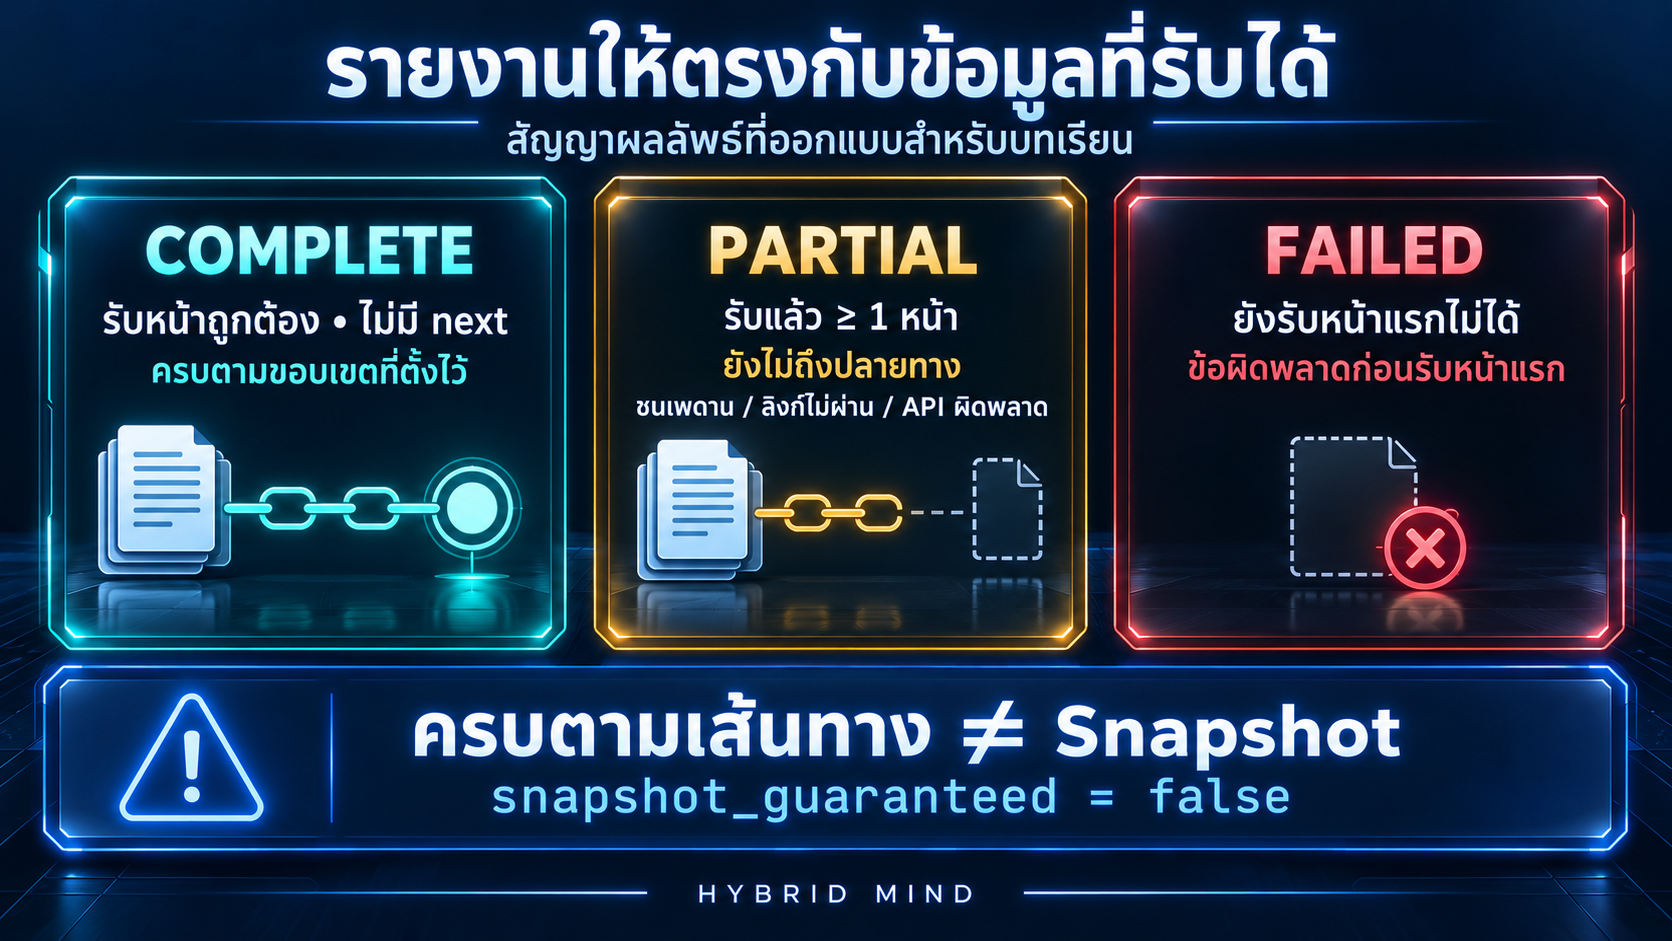
ทักษะของบทนี้คือออกแบบเครื่องมืออ่าน API หลายหน้าให้คืน COMPLETE, PARTIAL หรือ FAILED พร้อมหลักฐาน หากมีหน้าถัดไปแต่ชนเพดาน ให้ PARTIAL หากตรวจรับจนไม่มี next จึง COMPLETE ส่วน FAILED ใช้เมื่อมี error และยังไม่มีหน้ารายการที่รับได้
ตัวอย่างใช้ Python public GET ของ GitHub ตัวเลขและผลตัวอย่างเป็นข้อมูลสมมติ โค้ดกับ tests ยัง NOT RUN การเดินครบตามตัวกรองไม่รับประกันว่าข้อมูลทุกหน้าเป็น snapshot หรือภาพนิ่ง ณ เวลาเดียวกัน
ผลลัพธ์การเรียนรู้: คุณควรเขียน JSON ที่บอกสถานะ เหตุหยุด และส่วนที่ยังขาด แล้วตรวจรับกรณี API สำเร็จทุกคำขอแต่งานยังไม่ครบได้ เตรียมพื้นฐาน GET, JSON และ Python การอ่านบท/Lab ไม่ต้องมี API Key; การรันจริงต้องมี Python 3.12+ เครือข่ายและสิทธิ์เรียก GitHub สาธารณะ

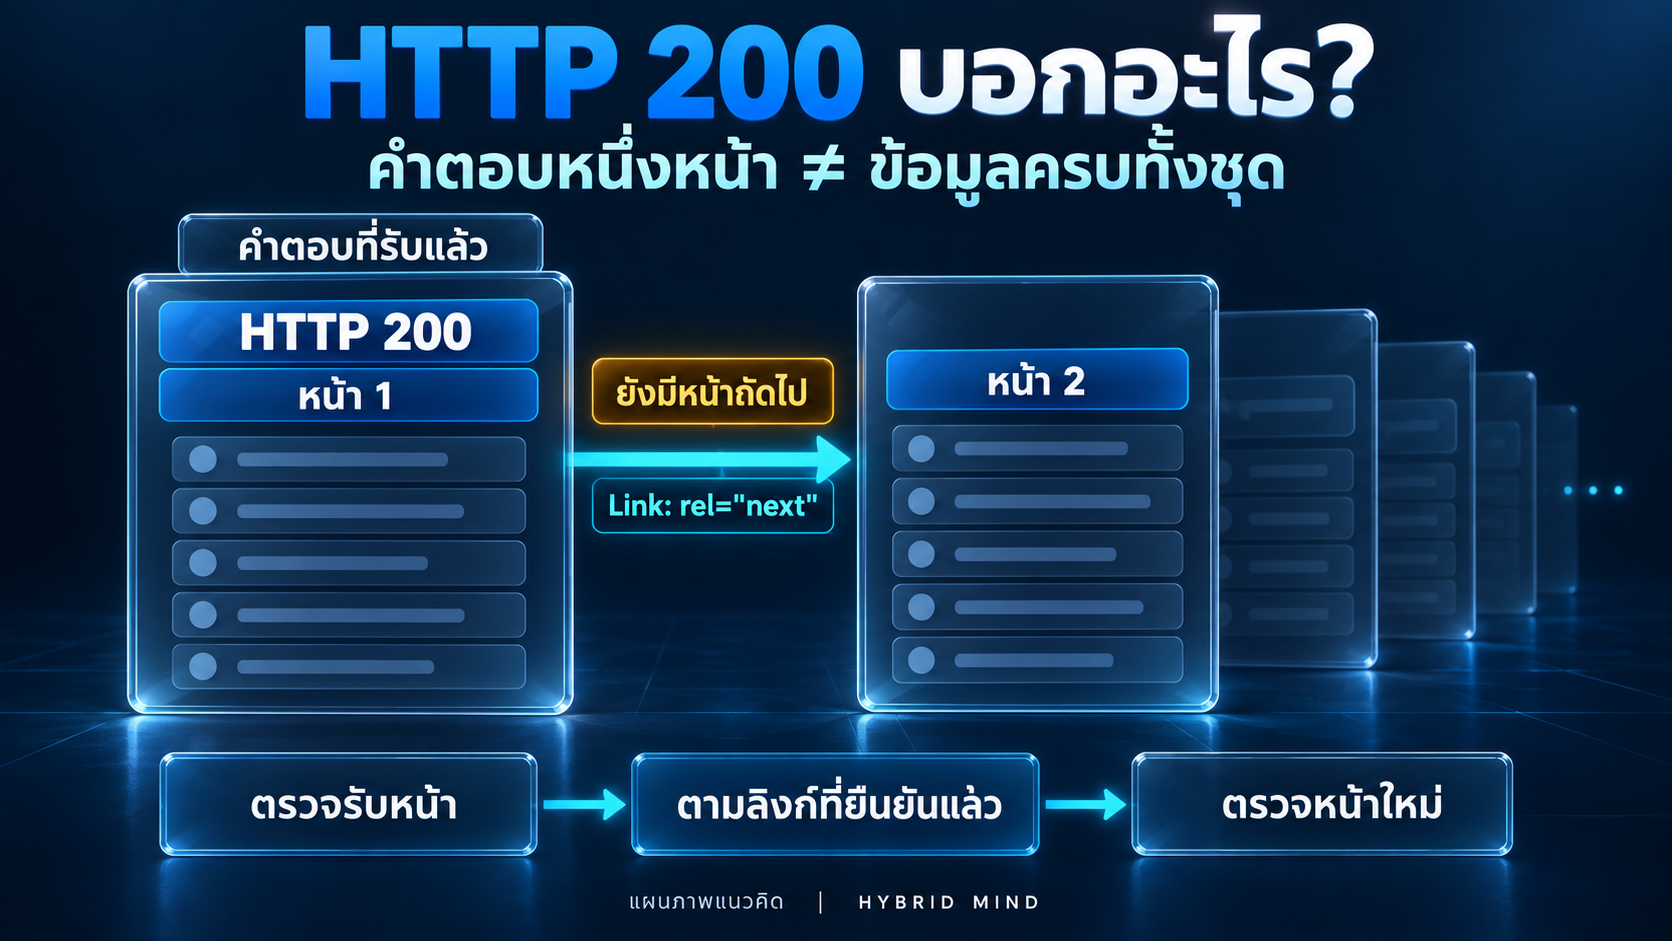
จาก LLM chat สู่ Agent ที่ต้องรับผิดชอบขอบเขตข้อมูล
LLM chat สรุปรายการที่คุณวางให้ได้ แต่ Agent ที่เรียกเครื่องมือเองต้องบอกแหล่ง ตัวกรอง หน้าที่อ่านและข้อมูลที่ยังขาด คำสั่ง “อ่านให้ครบ” ไม่สร้างหลักฐานให้ฟังก์ชันที่คืนแค่หน้าแรก
Pagination คือแบ่งผลลัพธ์เป็นหน้า Continuation คือทางอ่านต่อ เช่นลิงก์หรือ cursor ซึ่งเป็นตัวชี้ตำแหน่ง บทนี้ใช้ issue list ของ GitHub ไม่ใช่ตัวอ่านทุก API
GitHub อาจคืนผลเพียงบางส่วน และใช้ Link กับ rel="next" บอกหน้าต่อ Link อาจหายไปเมื่อผลอยู่ในหน้าเดียว ขนาดหน้าสูงสุดต้องดู endpoint โดยตรง เอกสาร Pagination
HTTP 200 ยืนยันการรับคำตอบครั้งนั้น ไม่ยืนยันการสำรวจทั้งชุด ใช้ Workflow ซึ่งเป็นลำดับคงที่เดินหน้า แล้วให้ Single-Agent หรือตัวเดียวสรุปผลได้ การเพิ่มหลาย Agent ยังไม่แก้สัญญาความครบของเครื่องมือ
Contract: นิยามคำว่าเสร็จก่อนเขียนลูป
Contract คือข้อตกลงระหว่างผู้เรียกกับผู้ตรวจรับ สถานะสามแบบนี้เป็นกรอบที่ผู้เขียนออกแบบสำหรับบทความ ไม่ใช่มาตรฐานบังคับของทุก API
| สถานะ | เงื่อนไข | สิ่งที่รายงานได้ |
|---|---|---|
| COMPLETE | รับ chain ถูกต้องจนตรวจรับว่าไม่มี next ไม่หยุดเพราะเพดาน/error | สิ้นสุดการเดินภายใต้ repository และ filter นี้ ไม่รับรอง snapshot |
| PARTIAL | รับอย่างน้อยหนึ่งหน้า แต่ติดเพดาน/error/continuation | ส่วนที่อ่านได้และส่วนที่ยังไม่รู้ |
| FAILED | มี error และยังไม่มีหน้ารายการที่รับได้ | เหตุผิดพลาด ไม่ใช่ “ไม่พบรายการ” |
parser หรือส่วนแยกข้อมูลต้องอ่าน Link ได้ก่อนตัดสินว่าไม่มี next หากอ่านไม่เป็น เรามีความไม่รู้ ไม่ใช่หลักฐานสิ้นสุด เช่นเดียวกับ error ที่ห้ามแปลงเป็น list ว่างสำเร็จ
ประโยชน์ของ PARTIAL คือยังส่งมอบส่วนที่ตรวจรับได้โดยไม่ปกปิดข้อจำกัด ผู้ใช้เลือกได้ว่าจะใช้ผลเบื้องต้นหรือมอบหมายรอบใหม่พร้อมเพดานที่เปลี่ยน ส่วน Agent ต้องรักษาคำเตือนนี้ในคำตอบ ไม่เพิ่มสิทธิ์หรือขยายงานเองเพียงเพื่อให้สถานะเป็น COMPLETE
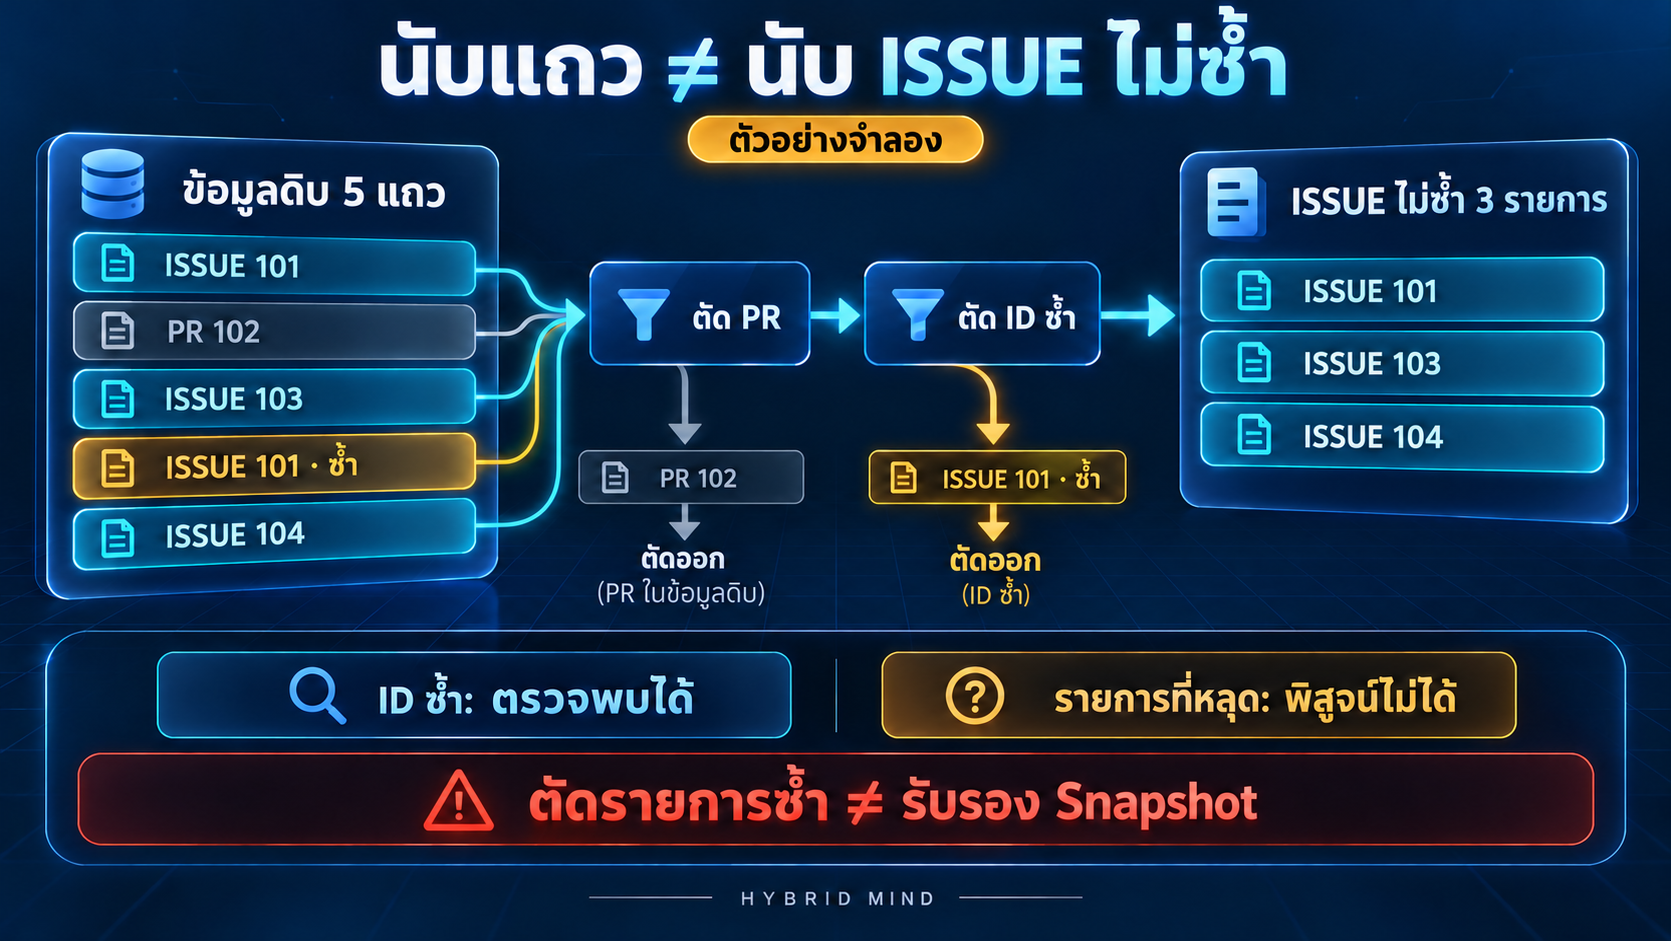
รายงานมี status, stop_reason, pages_accepted, raw_records_seen, unique_issues, next_page, แหล่ง ตัวกรองและเวลาเริ่ม–จบ คง snapshot_guaranteed=false raw นับแถวที่รับแล้วรวม PR; unique_issues ตัด PR และรหัสซ้ำ next_page ไม่รับประกันกลับมาอ่านภายหลังได้ชุดเดิม
Architecture: เครื่องมือเก็บหลักฐาน Agent เรียบเรียงผล
Data flow: คำสั่ง → ตรวจ repository ที่อนุญาต → metadata ยืนยันตัวตน → อ่าน/ตรวจหน้า → ประเมินทางต่อและเพดาน → รายงาน Metadata คือข้อมูลอธิบาย repository เช่นชื่อและรหัส
Get a repository ให้ id และ full_name อ่านข้อมูลสาธารณะได้โดยไม่ยืนยันตัวตน ตัวอย่างใช้ preflight หรือการตรวจเริ่มต้นหนึ่ง GET เพื่อจับคู่รหัสใน Link กับชื่อที่เลือก เอกสาร Metadata
Tool Calling คือโมเดลขอเรียกฟังก์ชันผ่านข้อมูลมีโครงสร้าง ให้ input รับเฉพาะ repository และเพดาน ห้ามส่ง URL ตามใจ output ต้องคงสถานะและเหตุผล ตัวอย่างยังไม่เชื่อมโมเดลจริง และไม่มี checkpoint สำหรับกลับมาหลังเครื่องดับ

Worked example: สำเร็จทุกคำขอ แต่ยังเป็น PARTIAL
คำสั่งสมมติ: “อ่าน open issues ของ psf/requests สำหรับทบทวนครั้งแรก รับไม่เกินสามหน้า หน้าละห้าแถว ห้ามแก้ repository ถ้ายังมีข้อมูลให้บอกว่าไม่ครบ” แผนคือยืนยันตัวตน แล้ว GET ทีละหน้า ตรวจข้อมูลและ continuation จนชนเพดาน
| หน้าสมมติ | แถว | PR | issue ซ้ำ | issue ใหม่ | ทางต่อ |
|---|---|---|---|---|---|
| 1 | 5 | 1 | 0 | 4 | หน้า 2 |
| 2 | 5 | 0 | 1 | 4 | หน้า 3 |
| 3 | 5 | 1 | 0 | 4 | หน้า 4 |
หลักฐานสมมติ: สิบห้าแถว ตัด PR สองกับ issue ซ้ำหนึ่ง เหลือสิบสอง issue แต่ยังมี next4 เพดานสามหน้าเป็นขอบเขตงาน ไม่ใช่จำนวนหน้าทั้งหมด
บางช่องของ JSON ที่คาดหวังจากข้อมูลสมมติ ไม่ใช่ log จริง:
{
  "status": "PARTIAL",
  "stop_reason": "MAX_PAGES_REACHED",
  "request_count": 4,
  "raw_records_seen": 15,
  "pull_request_records_excluded": 2,
  "duplicate_records_seen": 1,
  "unique_issues": 12,
  "next_page": 4,
  "snapshot_guaranteed": false
}
ตรวจรับ: คำตอบต้องบอกว่าอ่านได้สิบสอง issue จากสามหน้าและยังมีหน้าต่อ requests สี่รวม metadata ด้วย คำว่า “repository มีสิบสอง open issues” ไม่ผ่าน เพราะเปลี่ยนจำนวนที่เห็นเป็นยอดรวม
หน้าห้าแถวเต็มอาจ COMPLETE หากไม่มี next ที่ตรวจรับ ส่วนหน้าสองแถวต้องเดินต่อหากมี next อย่าใช้จำนวนแถวน้อยกว่าขนาดหน้าเป็นหลักฐานจบเอง
Implementation และ Code Walkthrough
โค้ดที่แสดงในบทประกอบด้วย pagination_tool.py, test_pagination_tool.py และ README ใช้ Python 3.12+ กับ Standard Library ที่มากับ Python ไม่ติดตั้ง dependency ไม่มี environment variable/API Key
ไฟล์หลักเป็น Live Integration: เมื่อรันจะ GET สาธารณะจริง แต่ผู้เขียนยังไม่ได้รัน ส่วน tests เป็น Synthetic Transport ที่ให้คำตอบสมมติแทนเครือข่าย ไม่ใช่ผล integration ที่ผ่านแล้ว
เมื่อได้รับสิทธิ์รัน วางสองไฟล์ใน directory เดียว ตรวจ runtime แล้วลอง tests ก่อนคำสั่ง Live:
python --version
python -m unittest -v test_pagination_tool.py
python pagination_tool.py psf/requests --max-pages 3
Input คือ psf/requests หรือ python/cpython หน้าละห้า max_pages หนึ่งถึงสาม อ่าน open issues เรียงเวลาสร้างเก่าไปใหม่ Live ใช้ quota ของ IP จึงอาจถูกจำกัด ไม่มีโมเดลเสียเงิน GPU หรือคำสั่งเขียนข้อมูล
collect ตั้งขอบเขตและตรวจ metadata; decode ตรวจ HTTP, media type, ขนาด body และ JSON; checked_rows ตรวจ identity และ repository หากแถวหนึ่งผิดจะปฏิเสธทั้งหน้า โดยคงหน้าก่อนหน้าที่ผ่านแล้ว
Issue-list อาจรวม pull request โดยมี pull_request ขนาดหน้าเริ่มต้น 30 สูงสุด 100 และ state เริ่มต้น open ตัวอย่างเลือกห้าเพื่อเรียนรู้ ไม่ใช่ข้อกำหนดบริการ เอกสาร Issues
continuation ตรวจทุก Link relation ก่อนตัดสินว่าไม่มี next: HTTPS บน api.github.com, path ตรงชื่อหรือ id ที่ยืนยัน, filter/ขนาดหน้าเดิมและความสัมพันธ์ของเลขหน้า แล้วตาม URL จริงที่ได้รับ หาก last ชี้หน้าที่ยังเกินปัจจุบันแต่ไม่มี next ถือว่าขัดกัน
ข้อมูลกับ continuation รับแยกกัน ถ้า body ถูกแต่ Link เสีย จะคงหน้าข้อมูลและคืน PARTIAL pages_accepted นับข้อมูลที่รับแล้ว ส่วน exhaustion_evidence มีเฉพาะหน้าที่ตรวจทางต่อสำเร็จ
RFC 8288 รองรับรูปแบบกว้างกว่า เช่น URI สัมพัทธ์และหลาย relation parser ตัวอย่างรับเฉพาะรูปแบบ GitHub ที่กำหนด รูปแบบอื่นหยุดอย่างตรงไปตรงมา ไม่ใช่ implementation ครบ RFC RFC 8288
ผู้เขียนตั้ง budget ยี่สิบวินาที ตรวจนาฬิกาก่อน–หลัง I/O และก่อนรับหน้า timeout ต่อ operation ไม่เกินห้าวินาที ตัวเลขเป็นนโยบายตัวอย่าง ไม่ใช่ผลวัด
urllib timeout ใช้กับ blocking operation ไม่ใช่ hard cancellation ของทั้งงาน เอกสาร Python 3.12.15
สามหน้าบวก metadata รวมไม่เกินสี่ HTTP attempts รับไม่เกินสิบห้า raw records body จำกัด 262,144 ไบต์ Link 16,384 ตัวอักษร ไม่หยุดครึ่งหน้าเพราะ item cap หากขนาดเกินต้องรายงานปัญหา ไม่ใช่ศูนย์รายการ ไม่มี retry อัตโนมัติ
Testing และ Verification
NOT RUN: เขียน synthetic test methods สิบเก้าข้อ ยังไม่ import, compile, รัน tests หรือเรียก GitHub Live ไม่มีผล runtime หรืออัตราความสำเร็จที่วัดแล้ว
Assertions ต้องจับความหมายผิด: full page ไม่มี next → COMPLETE; หน้าสามมี next → PARTIAL; หน้าแรกเสีย → FAILED; หน้าสองเสีย → คงหน้าแรก; Link ผิดปลายทางหรือ last ขัดกัน → ห้าม COMPLETE ตรวจ requests และข้อมูลที่คงไว้ด้วย ไม่เช็กแค่ list มีสมาชิก
Expected output คือค่าคาดหวังจาก fixture ที่ควบคุมได้ ไม่ยึดชื่อ issue จริงเป็น assertion ถาวร เพิ่ม evaluation หรือการประเมินผลให้โมเดลได้รับ PARTIAL แล้วตรวจคำตอบสุดท้ายว่ายังบอกข้อจำกัด Logs ควรมี execution id, scope, หน้าที่ขอ/รับ, เหตุหยุดและเวลา โดยไม่เก็บ body ส่วนบุคคลทั้งหมด

Failure modes และขอบเขต COMPLETE
หน้าแรก error คือ FAILED เมื่อยังไม่มีข้อมูลที่รับได้ หน้าสอง error คือ PARTIAL พร้อมหน้าแรกที่ยังใช้ได้ เพดานสามหน้าเมื่อมี next หรือ Link อ่านไม่เป็นก็เป็น PARTIAL ทั้งคู่ แต่เหตุหยุดและตำแหน่งต่ออาจต่างกัน
GitHub แนะนำใช้ Link เรียกทีละคำขอ และหยุดเมื่อ rate limit โดยดู Retry-After หรือ quota ศูนย์ ตัวอย่างหยุดรายงาน ไม่ยิงซ้ำ Best practices
deduplicate คือรวมรหัสซ้ำที่เห็น ไม่สร้างรายการที่หายไป การไม่มี duplicate จึงไม่พิสูจน์ว่าไม่มี omission งาน audit หรือยอดรวมที่ต้องแน่นอนควรมี snapshot จากต้นทาง ไม่ใช้ป้าย COMPLETE แทนหลักฐานนั้น
Stable sort ลดการสลับหน้าเมื่อแก้ข้อมูล แต่เพิ่ม/ลบรายการยังเลื่อนตำแหน่งได้ จึงคง snapshot_guaranteed=false ข้อจำกัดการเรียง
เริ่ม page4 ภายหลังไม่รับประกัน resume เดิม หากต้องการ exact inventory ต้องหา export หรือวิธีตรึงข้อมูลจากต้นทาง ซึ่งอยู่นอกตัวอย่าง
Security, Cost และ Production
Least privilege คือให้สิทธิ์เท่าที่จำเป็น: GET สอง repository สาธารณะ ไม่มี token ไม่อ่าน private ไม่แก้ issue ข้อความ title/Link เป็นข้อมูลภายนอก ไม่ใช่คำสั่งให้ Agent ส่งความลับ และต้อง escape เป็น plain text เมื่อแสดง HTML
GitHub แนะนำตาม redirect แต่ตัวอย่างหยุดที่ 301 ให้คนทบทวน allowlist เป็น tradeoff ของตัวอย่าง แนวทาง redirect
Control ที่ออกแบบยังไม่ใช่ Security Test ที่ผ่าน ต้องทดสอบ URL/query/body/identity ผิดและนโยบายเครือข่ายก่อน Production ไม่อ้างป้องกัน SSRF ทุกแบบหรือการหลอกให้เรียกปลายทางอื่น ต้นทุนขึ้นกับหน้า body และ token ที่ส่งโมเดล ยังไม่วัดราคา latency หรือความประหยัด
ใช้เครื่องมือสำเร็จรูปได้เมื่อรายงานขอบเขตและ partial status ตรง acceptance การมี connector ไม่ยืนยันว่ามันอ่านครบทุกหน้า
Brief คัดลอกได้ครบหกส่วน
ข้อเสนอแนะการมอบหมายนี้ไม่สั่งให้บทความหรือ Lab เรียก API ของคุณ:
เป้าหมาย: อ่าน open issues ของ psf/requests และรายงานความครบอย่างตรงไปตรงมา
ข้อมูล/เครื่องมือ: public GitHub metadata GET + issue-list GET รุ่น API2026-03-10; Python3.12+ Standard Library; fixtures สำหรับทดสอบ
ขอบเขตสิทธิ์: เขียนก่อน ไม่รันโดยไม่มีสิทธิ์; เมื่ออนุญาต Live อ่านเท่านั้น ไม่มี token ไม่ตาม redirect ไม่ออก allowlist ไม่แก้ issue
สิ่งส่งมอบ: โค้ด README tests และ JSON พร้อม status stop_reason scope pages_accepted raw_records_seen unique_issues next_page snapshot_guaranteed
เกณฑ์ตรวจรับ: หน้าละห้า สูงสุดสาม; รวม metadataไม่เกินสี่ requests; มี nextหลังหน้าสามต้อง PARTIAL; errorก่อนมีหน้าที่รับต้อง FAILED; COMPLETEต้องมี exhaustion evidence; snapshot_guaranteed=false
จุดหยุด/ส่งให้คน: HTTPerror serverwait JSON/identity/Linkผิด ขนาดเกิน เพดานหน้า เวลาเกินหรือปลายทางเปลี่ยน; คืนส่วนที่รับแล้วพร้อมเหตุ ไม่เดาข้อมูลที่ขาด
แบบฝึกหนึ่งข้อ
จากตารางสามหน้าสมมติ เขียน JSON และคำตอบสองประโยค: สิ่งที่เห็นกับข้อจำกัด แล้วเปลี่ยน input ให้หน้าสองตอบ 503 โดยหน้าหนึ่งมีห้าแถวรวม PR หนึ่ง อธิบายสถานะและจำนวนที่เปลี่ยน
Rubric หรือเกณฑ์ตรวจรับ: ฉบับแรก PARTIAL/MAX_PAGES_REACHED, raw15, unique12, next4 ฉบับที่เปลี่ยน PARTIAL/HTTP_503, รับหนึ่งหน้า, raw5, unique4 ไม่รวมหน้าที่ error ทั้งคู่ snapshot_guaranteed=false และไม่เรียกจำนวนที่เห็นว่ายอดรวมจริง อย่าเรียก Live เพื่อหาตัวเลขให้ตรง fixture
Practical checklist
- ระบุ collection/filter/permission/เพดาน
- ตรวจ continuation และ scope ก่อนอ่านต่อ
- แยก raw, issue, PR และ duplicate
- error ไม่กลายเป็น empty success
- complete ต้องมี exhaustion evidence
- คงข้อจำกัด snapshot และ test status
ลองเปลี่ยนขอบเขต: อ่านได้กี่หน้า แล้วควรรายงานว่าอะไร?
SIMULATION — ข้อมูลสมมติทั้งหมด Lab นี้แบ่งอาร์เรย์ที่สร้างขึ้นในหน้าเว็บเป็นหน้าตามลำดับ ไม่มีการเรียก GitHub, LLM หรือ API จริง จำนวนรายการและหน้าเป็นค่าที่ผู้ใช้ตั้ง ไม่ใช่ผลวัดระบบจริง
เป้าหมายคือแยก HTTP 200 ของหนึ่งหน้าออกจากการอ่านครบชุด เริ่มจาก 12 รายการ หน้าละ 5 รายการ แต่งบรับได้ 2 หน้า: รับ 10 รายการแล้วต้องบอก PARTIAL เพราะยังมีหน้าที่ 3 ให้ลองเพิ่มงบเป็น 3 หน้า แล้วจำลองข้อผิดพลาดที่หน้า 1 และหน้า 2 เพื่อดูความต่างของ FAILED กับ PARTIAL
3D Page Stack — หน้าที่รับแล้ว กับหน้าที่ยังไม่ได้รับ
แผ่นแต่ละใบแทนหนึ่งหน้าของชุดข้อมูล สีฟ้าพร้อมคำว่า “รับแล้ว” คือหน้าที่ตอบสำเร็จและผ่านเงื่อนไขก่อนรับทั้งหน้า สีส้มคือหน้าที่เกิดข้อผิดพลาด สีเทาคือหน้าที่ยังไม่อ่าน การอ่านครบไม่รับประกันว่าแหล่งข้อมูลจริงหยุดเปลี่ยนแปลง
- หน้า 1 · รับแล้วตำแหน่ง 1–5 · 5 รายการ200 + ผ่านเงื่อนไข · มีหน้าถัดไป
- หน้า 2 · รับแล้วตำแหน่ง 6–10 · 5 รายการ200 + ผ่านเงื่อนไข · มีหน้าถัดไป
- หน้า 3 · ยังไม่อ่านตำแหน่ง 11–12 · 2 รายการยังไม่มีหลักฐานตอบกลับของหน้านี้
แบบจำลองเริ่มต้น: รับแล้ว 2 หน้า / 10 รายการ · เหลือ 2 รายการที่รู้จากข้อมูลสมมติ · หยุดเพราะงบหน้า
ผังใช้ CSS 3D กับข้อความใน DOM โดยไม่ใช้ canvas หากเบราว์เซอร์ไม่แสดงความลึกยังอ่านลำดับหน้าและสถานะจากข้อความได้
Visual Interactive แยก: Pagination Contract Inspector
ปรับค่าแล้วออกจากช่องเพื่ออ่านผลด้านล่าง หรือกด “คำนวณสถานการณ์” คีย์บอร์ดใช้ Tab เพื่อย้ายช่องและปุ่มลูกศรเพื่อปรับตัวเลข Error หลังรับหน้าก่อนหน้าแล้วจะเป็น PARTIAL เสมอ ไม่เปลี่ยนเป็น FAILED เพียงเพราะชื่อสถานการณ์เป็น failure
สถานะเริ่มต้นที่อ่านได้โดยไม่ใช้ JavaScript แสดงอยู่ด้านล่าง หากตัวควบคุมไม่เปลี่ยนผล ให้อ่านตารางกติกาแทน
PARTIAL PAGE_BUDGET — ยังมีหน้าถัดไป แต่งบรับหน้าเต็มแล้ว
- รายการดิบที่รับ
- 10 รายการ
- หน้าที่รับทั้งหน้า
- 2 หน้า
- เหลือในข้อมูลสมมติ
- 2 รายการ
- หน้าต่อที่ยังไม่ได้รับ
- 3
ใช้ 10 รายการที่รับแล้วเป็นข้อมูลบางส่วน พร้อมบอกขอบเขตและเหตุผลหยุด ห้ามสรุปว่าอ่านครบ 12 รายการ
{
  "classification": "SIMULATION",
  "state": "PARTIAL",
  "raw_count": 10,
  "accepted_pages": 2,
  "remaining_known_simulation": 2,
  "next_page": 3,
  "stop_reason": "PAGE_BUDGET",
  "snapshot_guaranteed": false
}
Lab รู้จำนวนที่เหลือเพราะสร้างชุดข้อมูลสมมติเอง API จริงอาจไม่บอกจำนวนทั้งหมด ต้องรายงานว่า ยังไม่ทราบ แทนการคำนวณยอดที่ไม่มีหลักฐาน คำว่า COMPLETE ในตอนนี้หมายถึงอ่านถึงหน้าสุดท้ายที่รับและไม่มี next ภายใต้ขอบเขตนี้เท่านั้น snapshot_guaranteed=false ในทุกผล
| สิ่งที่เกิดขึ้น | ผลตาม contract |
|---|---|
| รับหน้าที่ถูกต้องจนไม่มี next | COMPLETE · END_NO_NEXT · snapshot ไม่รับประกัน |
| ยังมี next แต่งบหน้าครบ | PARTIAL · PAGE_BUDGET |
| Error หลังรับอย่างน้อยหนึ่งหน้า | PARTIAL · SIMULATED_PAGE_ERROR · คงเฉพาะหน้าที่รับแล้ว |
| Error ก่อนรับหน้าแรก | FAILED · SIMULATED_PAGE_ERROR · 0 หน้าที่รับ |
| ชุดข้อมูลว่าง รับหน้าแรกที่ถูกต้องและไม่มี next | COMPLETE · รับ 1 หน้า · 0 รายการ |
สัญลักษณ์สถานะเป็นกติกาที่ผู้เขียนออกแบบ ไม่ใช่ผลทดสอบโค้ด Python หรือการรับรอง production การทดสอบปุ่ม หน้าจอ และ accessibility จริงยัง UNKNOWN
นำ contract เดียวกันไปใช้กับงานวิดีโอ
Video Lab ต่อไปจำลองวงจรวางแผนและผลิตวิดีโอ ให้นึกถึงขั้นรวบรวมคลิปหรือข้อมูลจาก API ที่แบ่งหน้า ก่อนเลือกช่วงตัดต่อ ถ้าเครื่องมือคืน PARTIAL แผนตัดต่อควรจำกัดว่าใช้เฉพาะรายการที่รับแล้ว และส่งประเด็นที่ยังขาดให้คน ไม่เปลี่ยนคำว่า “ได้รายการมาแล้ว” เป็น “รวบรวมครบแล้ว”
- เลือกหัวข้อวิดีโอ “Agent อ่านข้อมูลครบหรือยัง?” และรูปแบบที่ต้องการใน Lab
- ใช้ผลจำลองข้างบนเป็นเงื่อนไขของขั้นรวบรวมแหล่งข้อมูล: COMPLETE จึงวางแผนภายใต้ขอบเขตนั้น; PARTIAL/FAILED ให้ระบุสิ่งขาดและจุดหยุด
- อ่าน prompt ที่ Lab สร้าง เทียบกับ brief หกส่วนด้านล่าง แล้วเติมส่วนที่ขาดด้วยตนเอง ไม่ถือว่า generator ใส่สิทธิ์ เกณฑ์ตรวจรับ และจุดหยุดครบอัตโนมัติ
Video Lab เป็น simulation ค่าเวลาและเงินที่ปรับเป็นสมมติฐาน ไม่ใช่ผลวัดจริง การทดลองนี้ไม่ให้สิทธิ์เรียก API ดาวน์โหลดไฟล์ เผยแพร่ หรือส่งวิดีโอจริง
Brief หกส่วน — อ่านและคัดลอกด้วยตนเองได้
- 1. เป้าหมาย
- เขียนแผนวิดีโอสอนว่า HTTP 200 ของหนึ่งหน้าไม่เท่ากับอ่านข้อมูลครบชุด โดยอธิบาย COMPLETE, PARTIAL และ FAILED
- 2. ข้อมูลและเครื่องมือ
- ใช้รายการคลิปสมมติ 12 รายการ แบ่งหน้าละ 5 รายการ พร้อมผล Pagination Contract Inspector และ Video Lab สำหรับร่างลำดับงานเท่านั้น
- 3. ขอบเขตสิทธิ์
- อ่านข้อมูลสมมติและร่างข้อความได้ ไม่เรียก API จริง ไม่ดาวน์โหลด ไม่แก้ไฟล์หรือข้อมูลภายนอก ไม่เผยแพร่และไม่ติดต่อบุคคล
- 4. สิ่งส่งมอบ
- แผนฉากพร้อมรายการแหล่งข้อมูลที่รับแล้ว จำนวนหน้าที่รับ state, stop_reason, ข้อมูลที่ยังขาด และ snapshot_guaranteed=false
- 5. เกณฑ์ตรวจรับ
- จำนวนรายการตรงกับหน้าที่รับทั้งหน้า ไม่รวมหน้าที่ error/ยังไม่อ่าน; ถ้ามี next ต้องไม่อ้าง COMPLETE; ผลสมมติแยกจากหลักฐานจริง และ brief ครบทั้งหกส่วน
- 6. จุดหยุดและส่งให้คน
- ถ้า PARTIAL/FAILED ให้ส่งรายการที่รับแล้วพร้อมเหตุผลและสิ่งขาดแก่ผู้ตรวจ ไม่ขยายงบหน้าเอง ไม่แต่งแหล่งข้อมูลเพิ่ม และไม่เริ่มผลิตหรือเผยแพร่วิดีโอจริง
จากคลิปดิบ
สู่จักรวาลคอนเทนต์
ChatGPT ตัดต่อวิดีโอแทนคนได้จริงแค่ไหน? สำรวจระบบ AI Video Editing Agent ผ่านฉากสามมิติที่โต้ตอบได้ พร้อมแยกข้อเท็จจริง สร้างพรอมป์ต์ และจำลองต้นทุนก่อนลงมือทำจริง
ออกแบบระบบตัดต่อในมุมมอง 3D
ลากบนฉากเพื่อหมุนมุมมอง แตะโหนดเพื่อดูหน้าที่ของ AI ในแต่ละขั้นตอน
จัดระเบียบไฟล์ ตรวจคุณภาพภาพและเสียง และกำหนดสิทธิ์เข้าถึงให้ AI Agent
แยกความสามารถจริงจากคำโฆษณา
กดแต่ละประเด็นเพื่ออ่านรายละเอียดและแหล่งข้อมูล
ChatGPT Work เข้าถึงไฟล์ในเครื่องได้ตรวจสอบแล้ว / มีเงื่อนไข+
Astra ใช้โปรแกรมคอมพิวเตอร์ทำงานได้ตรวจสอบแล้ว / ไม่ใช่โปรแกรมตัดต่อในตัว+
ตัดเสร็จใน 5–10 นาทีทุกกรณียังพิสูจน์เป็นเกณฑ์ทั่วไปไม่ได้+
ถูกกว่าจ้างคน 10 เท่าต้องกำหนดต้นทุนให้เทียบกันได้+
หนึ่งไอเดีย สามรูปแบบคอนเทนต์
ปรับรูปแบบวิดีโอ แล้วดูกรอบภาพตัวอย่างและ Prompt เปลี่ยนตามแบบเรียลไทม์
ช่วยตัดต่อ?
พร้อมนำไปใช้กับ AI Agent
ตัวสร้าง Prompt นี้ไม่อัปโหลดคลิป ไม่เรียก API เสียเงิน และไม่ตัดต่อวิดีโอจริง ต้องใช้กับเครื่องมือที่ผู้ใช้อนุญาตภายหลัง
จำลองเวลาและต้นทุนของคุณเอง
เลื่อนตัวเลขเพื่อเปรียบเทียบสถานการณ์สมมติ ไม่ใช่ผล benchmark ที่ยืนยันแล้ว
ตัวเลขเป็นตัวอย่างเพื่อช่วยตัดสินใจ ไม่ใช่ผลประหยัดที่รับประกัน
AI ที่ตัดคลิปเป็น ไม่ได้ทำงานลำพัง
สิ่งที่น่าสนใจของ GPT-6 Astra และ GPT-6.1 Sol ไม่ได้อยู่ที่ว่าตัวโมเดลมีปุ่ม Render MP4 ซ่อนอยู่ แต่คือความสามารถในการจัดการงานหลายขั้นตอนร่วมกับเครื่องมืออื่น: อ่านไฟล์ วางลำดับเรื่อง ใช้แอป ตรวจผลลัพธ์ และแก้งานตามข้อเสนอแนะของมนุษย์
สำหรับคนทำคอนเทนต์ ความต่างสำคัญคือการเปลี่ยนจาก “ส่งคลิปให้ AI แล้วหวังว่าจะได้ผลงาน” ไปเป็น Workflow ที่ตรวจรับได้ทุกขั้น ตั้งแต่การเลือกช่วงเด็ด การสร้างซับ การตรวจคำผิด จนถึงการเรนเดอร์ไฟล์ตามสัดส่วนของแต่ละแพลตฟอร์ม
ข้อควรระวังคือระบบ Work ที่รันบนเว็บหรือมือถือไม่ได้หมายความว่า AI เข้าถึงคลิปบนคอมพิวเตอร์บ้านได้ทันที ต้องทำงานในสภาพแวดล้อมที่เปิดให้เข้าถึงไฟล์จริง มีเครื่องมือตัดต่อ และมีสิทธิ์ใช้งานอย่างชัดเจน
รวบรวมไฟล์ในโฟลเดอร์ที่เข้าถึงได้ ระบุสิทธิ์และข้อจำกัด
ให้ Agent เสนอ Hook, ช่วงตัด และโครงเรื่องก่อนตัดต่อ
ตรวจชื่อเฉพาะ ตัวเลข ภาษาไทย และความถูกต้องของคำกล่าวอ้าง
ตรวจความละเอียด เสียง ระยะเวลา safe zone และคำบรรยาย
หาก canvas หรือ JavaScript ของ Video Lab ใช้ไม่ได้ ให้อ่านลำดับงานและ brief หกส่วนข้างบน แล้วร่างแผนฉากจากรายการที่รับแล้วบนกระดาษ การอ่านข้อความแทนนี้ไม่ใช่หลักฐานว่าทดสอบ Lab ผ่าน
FAQ
HTTP 200 และ JSON ถูก ยัง FAILED ได้ไหม
ได้ หาก identity ของหน้าแรกผิดจนยังไม่มีหน้ารายการที่รับได้ metadata สำเร็จไม่เท่ากับรับ issue page สำเร็จ
COMPLETE ครอบคลุมอะไร
chain ของ repository และ filter ในงานครั้งนี้ ไม่ครอบคลุม repository อื่น closed issues หรือ snapshot ที่ตรึงเวลา
dedup แล้ว snapshot_guaranteed เป็น true ได้ไหม
ไม่ได้ ตัดซ้ำไม่พิสูจน์ว่าไม่มีข้อมูลหาย ต้องมีหลักฐานจากต้นทาง
ทำไม PARTIAL แต่ next_page เป็น null
เมื่อ Link อ่านไม่เป็น ตำแหน่งต่อยังไม่ทราบ อ่าน status กับ stop_reason ร่วมกัน อย่าตีความ null ว่าข้อมูลหมด
โค้ดและ Lab ทดสอบแล้วหรือยัง
โค้ด/tests ยัง NOT RUN ปุ่มและหน้าจอ Lab จริงยัง UNKNOWN การตรวจเอกสารกับการออกแบบไม่ใช่ runtime PASS
Source Code: pagination_tool.py — NOT RUN
"""Bounded public GitHub issue collection. Teaching example; tests NOT RUN.

No LLM, write API, credentials, redirects, retries or production claim.
Python 3.12+ / standard library. Live invocation makes real public GETs.
"""
from __future__ import annotations

import argparse
from dataclasses import dataclass
from datetime import datetime, timezone
import json
import re
import time
from typing import Callable
from urllib.error import HTTPError, URLError
from urllib.parse import parse_qsl, urlencode, urlsplit
from urllib.request import HTTPRedirectHandler, ProxyHandler, Request, build_opener

ALLOWED_REPOS = {"psf/requests", "python/cpython"}
API = "https://api.github.com"
API_VERSION = "2026-03-10"
PER_PAGE = 5
MAX_BODY_BYTES = 262_144
MAX_LINK_CHARS = 16_384
FILTERS = {"state": "open", "sort": "created", "direction": "asc"}


class Stop(Exception):
    def __init__(self, reason: str):
        self.reason = reason
        super().__init__(reason)


@dataclass(frozen=True)
class Reply:
    status: int
    headers: dict[str, str]
    body: bytes


class NoRedirect(HTTPRedirectHandler):
    def redirect_request(self, req, fp, code, msg, headers, newurl):
        return None


def live_get(url: str, timeout: float) -> Reply:
    # Disabling proxy discovery is an explicit teaching boundary, not SSRF proof.
    opener = build_opener(ProxyHandler({}), NoRedirect())
    req = Request(url, method="GET", headers={
        "Accept": "application/vnd.github+json",
        "X-GitHub-Api-Version": API_VERSION,
        "User-Agent": "hybridmind-pagination-teaching/1.0",
    })
    try:
        with opener.open(req, timeout=timeout) as response:
            headers = {k.lower(): v for k, v in response.headers.items()}
            links = response.headers.get_all("Link", [])
            if links:
                headers["link"] = ", ".join(links)
            return Reply(response.status, headers, response.read(MAX_BODY_BYTES + 1))
    except HTTPError as exc:
        with exc:
            return Reply(exc.code, {k.lower(): v for k, v in exc.headers.items()}, b"")
    except (URLError, TimeoutError, OSError) as exc:
        raise Stop("NETWORK_ERROR") from exc


def no_constant(value):
    raise ValueError("Non-finite JSON constant")


def no_duplicate_keys(pairs):
    result = {}
    for key, value in pairs:
        if key in result:
            raise ValueError("Duplicate JSON key")
        result[key] = value
    return result


def decode(reply: Reply):
    if reply.status != 200:
        raise Stop(f"HTTP_{reply.status}")
    if len(reply.body) > MAX_BODY_BYTES:
        raise Stop("BODY_TOO_LARGE")
    media = reply.headers.get("content-type", "").split(";", 1)[0].strip().lower()
    if media not in {"application/json", "application/vnd.github+json"}:
        raise Stop("UNEXPECTED_CONTENT_TYPE")
    try:
        return json.loads(reply.body.decode("utf-8"), parse_constant=no_constant,
                          object_pairs_hook=no_duplicate_keys)
    except (UnicodeError, ValueError, RecursionError) as exc:
        raise Stop("INVALID_JSON") from exc


def positive_int(value) -> bool:
    return type(value) is int and value > 0


def repository_id(data, repo: str) -> int:
    if (not isinstance(data, dict) or not positive_int(data.get("id"))
            or not isinstance(data.get("full_name"), str)
            or data["full_name"].lower() != repo
            or data.get("private") is not False
            or data.get("url") != f"{API}/repos/{repo}"):
        raise Stop("REPOSITORY_IDENTITY_INVALID")
    return data["id"]


def checked_rows(data, repo: str, rid: int):
    if not isinstance(data, list) or len(data) > PER_PAGE:
        raise Stop("PAGE_SCHEMA_INVALID")
    result = []
    repo_urls = {f"{API}/repos/{repo}", f"{API}/repositories/{rid}"}
    for row in data:
        if (not isinstance(row, dict) or not positive_int(row.get("id"))
                or not positive_int(row.get("number"))
                or row.get("repository_url") not in repo_urls
                or row.get("state") != "open"
                or not isinstance(row.get("title"), str)
                or len(row["title"]) > 4096):
            raise Stop("ITEM_IDENTITY_INVALID")
        is_pr = "pull_request" in row
        if is_pr and not isinstance(row["pull_request"], dict):
            raise Stop("ITEM_IDENTITY_INVALID")
        expected = f"https://github.com/{repo}/{'pull' if is_pr else 'issues'}/{row['number']}"
        if row.get("html_url") != expected:
            raise Stop("ITEM_URL_INVALID")
        result.append({"id": row["id"], "number": row["number"],
                       "title": row["title"], "url": expected, "is_pr": is_pr})
    return result


def continuation(header: str | None, repo: str, rid: int, page: int) -> str | None:
    """Narrow documented GitHub Link layout, NOT a general RFC 8288 parser.

    Unsupported syntax is an honest stop, never absence-of-next evidence.
    All entries must be common absolute-URL ; rel="one relation" form.
    """
    if header is None:
        return None
    if not header.strip() or len(header) > MAX_LINK_CHARS:
        raise Stop("LINK_UNSUPPORTED")
    links = {}
    seen_rel = set()
    for entry in header.split(","):
        match = re.fullmatch(r'\s*<([^<>\s,]+)>\s*;\s*rel\s*=\s*"(next|prev|first|last)"\s*', entry)
        if not match or match[2] in seen_rel:
            raise Stop("LINK_UNSUPPORTED")
        seen_rel.add(match[2])
        candidate, relation = match[1], match[2]
        try:
            parsed = urlsplit(candidate)
            pairs = parse_qsl(parsed.query, keep_blank_values=True, strict_parsing=True)
            query = dict(pairs)
            page_text = query.get("page", "")
            if not re.fullmatch(r"[1-9][0-9]{0,9}", page_text):
                raise Stop("LINK_UNSUPPORTED")
            linked_page = int(page_text)
            paths = {f"/repos/{repo}/issues", f"/repositories/{rid}/issues"}
            expected = dict(FILTERS, per_page=str(PER_PAGE), page=page_text)
            if (parsed.scheme != "https" or parsed.netloc != "api.github.com"
                    or parsed.path not in paths or parsed.fragment
                    or len(pairs) != len(query) or query != expected):
                raise Stop("LINK_OUT_OF_SCOPE")
            if ((relation == "next" and linked_page != page + 1)
                    or (relation == "prev" and linked_page != page - 1)
                    or (relation == "first" and linked_page != 1)
                    or (relation == "last" and linked_page < page)):
                raise Stop("LINK_INCONSISTENT")
            links[relation] = (candidate, linked_page)
        except ValueError as exc:
            raise Stop("LINK_UNSUPPORTED") from exc
    if "next" not in links:
        if "last" in links and links["last"][1] > page:
            raise Stop("LINK_INCONSISTENT")
        return None
    if "last" in links and links["last"][1] < links["next"][1]:
        raise Stop("LINK_INCONSISTENT")
    return links["next"][0]  # Actual validated Link; never a guessed next query.


def utc_now() -> str:
    return datetime.now(timezone.utc).isoformat()


def collect(repo: str, *, max_pages: int = 3, budget_seconds: float = 20.0,
            fetch: Callable[[str, float], Reply] = live_get,
            clock: Callable[[], float] = time.monotonic) -> dict:
    if repo not in ALLOWED_REPOS:
        raise ValueError("Repository is not allowlisted")
    if type(max_pages) is not int or not 1 <= max_pages <= 3:
        raise ValueError("max_pages must be 1..3")
    if type(budget_seconds) not in (int, float) or not 0 < budget_seconds <= 60:
        raise ValueError("budget_seconds must be >0 and <=60")
    started = utc_now()
    deadline = clock() + budget_seconds
    page = 1
    pages = []
    issues = {}
    seen_ids = {}
    seen_numbers = {}
    raw_count = pr_count = duplicate_count = request_count = 0
    status, reason = "FAILED", "NOT_STARTED"
    next_page = None
    rid = None
    endpoint = f"{API}/repos/{repo}/issues"
    evidence = []
    warnings = []

    def get(url):
        nonlocal request_count
        remaining = deadline - clock()
        if remaining <= 0:
            raise Stop("TIME_BUDGET_EXHAUSTED")
        request_count += 1
        reply = fetch(url, min(5.0, remaining))
        if clock() >= deadline:
            raise Stop("TIME_BUDGET_EXHAUSTED")
        return Reply(reply.status, {k.lower(): v for k, v in reply.headers.items()}, reply.body)

    try:
        meta_reply = get(f"{API}/repos/{repo}")
        rid = repository_id(decode(meta_reply), repo)
        if (meta_reply.headers.get("retry-after") is not None
                or meta_reply.headers.get("x-ratelimit-remaining") == "0"):
            raise Stop("SERVER_WAIT_REQUIRED")
        next_page = 1
        url = endpoint + "?" + urlencode(dict(FILTERS, per_page=PER_PAGE, page=1))
        while True:
            reply = get(url)
            rows = checked_rows(decode(reply), repo, rid)
            # Reject an inconsistent page atomically, retaining only earlier pages.
            page_ids, page_numbers = dict(seen_ids), dict(seen_numbers)
            for row in rows:
                identity = (row["number"], row["is_pr"])
                if ((row["id"] in page_ids and page_ids[row["id"]] != identity)
                        or (row["number"] in page_numbers and page_numbers[row["number"]] != row["id"])):
                    raise Stop("CONFLICTING_IDENTITY")
                page_ids[row["id"]] = identity
                page_numbers[row["number"]] = row["id"]
            if clock() >= deadline:
                raise Stop("TIME_BUDGET_EXHAUSTED")
            for row in rows:
                if row["id"] in seen_ids:
                    duplicate_count += 1
                if row["is_pr"]:
                    pr_count += 1
                else:
                    issues[row["id"]] = {k: row[k] for k in ("id", "number", "title", "url")}
                seen_ids[row["id"]] = (row["number"], row["is_pr"])
                seen_numbers[row["number"]] = row["id"]
            raw_count += len(rows)
            pages.append({"page": page, "raw_records": len(rows), "url": url})
            next_page = None  # Until a trustworthy continuation is validated.
            following = continuation(reply.headers.get("link"), repo, rid, page)
            evidence.append({"page": page, "http_status": 200,
                             "continuation": "NEXT" if following else "NO_NEXT_ACCEPTED"})
            if following is None:
                status, reason = "COMPLETE", "NO_NEXT_LINK"
                break
            next_page = page + 1
            if (reply.headers.get("retry-after") is not None
                    or reply.headers.get("x-ratelimit-remaining") == "0"):
                raise Stop("SERVER_WAIT_REQUIRED")
            if len(pages) >= max_pages:
                raise Stop("MAX_PAGES_REACHED")
            page += 1
            url = following
    except Stop as exc:
        status = "PARTIAL" if pages else "FAILED"
        reason = exc.reason
    if duplicate_count:
        warnings.append("DUPLICATES_OBSERVED_NO_SNAPSHOT_GUARANTEE")
    return {
        "status": status, "stop_reason": reason, "repository": repo,
        "repository_id": rid, "source_endpoint": endpoint,
        "filters": dict(FILTERS), "per_page": PER_PAGE, "max_pages": max_pages,
        "request_count": request_count, "pages_accepted": pages,
        "raw_records_seen": raw_count, "pull_request_records_excluded": pr_count,
        "duplicate_records_seen": duplicate_count, "unique_issues": len(issues),
        "issues": list(issues.values()), "next_page": next_page,
        "exhaustion_evidence": evidence, "warnings": warnings,
        "started_at_utc": started, "finished_at_utc": utc_now(),
        "snapshot_guaranteed": False,
        "scope": "Public open issues in this repository; page traversal, not an immutable inventory",
    }


if __name__ == "__main__":
    parser = argparse.ArgumentParser(description=__doc__)
    parser.add_argument("repository", choices=sorted(ALLOWED_REPOS))
    parser.add_argument("--max-pages", type=int, default=3, choices=(1, 2, 3))
    args = parser.parse_args()
    print(json.dumps(collect(args.repository, max_pages=args.max_pages),
                     ensure_ascii=False, indent=2))
Source Code: test_pagination_tool.py — NOT RUN
"""Authored synthetic tests. NOT RUN. Never requests live network resources."""
import json
import unittest

from pagination_tool import API, FILTERS, PER_PAGE, Reply, collect, continuation
from urllib.parse import urlencode

REPO = "psf/requests"
RID = 123


def response(data, link=None, **extra_headers):
    headers = {"content-type": "application/json", **extra_headers}
    if link is not None:
        headers["link"] = link
    return Reply(200, headers, json.dumps(data).encode())


def meta(**overrides):
    return response({"id": RID, "full_name": REPO, "private": False,
                     "url": f"{API}/repos/{REPO}", **overrides})


def row(n, *, pr=False, **overrides):
    record = {"id": n + 1000, "number": n, "repository_url": f"{API}/repos/{REPO}",
              "state": "open", "title": f"Synthetic item {n}",
              "html_url": f"https://github.com/{REPO}/{'pull' if pr else 'issues'}/{n}"}
    if pr:
        record["pull_request"] = {"url": f"{API}/repos/{REPO}/pulls/{n}"}
    record.update(overrides)
    return record


def next_link(page, *, numeric=False, **overrides):
    query = dict(FILTERS, per_page=PER_PAGE, page=page)
    query.update(overrides)
    path = f"/repositories/{RID}/issues" if numeric else f"/repos/{REPO}/issues"
    return f'<{API}{path}?{urlencode(query)}>; rel="next"'


class SyntheticTransport:
    def __init__(self, replies):
        self.replies = list(replies)
        self.requests = []

    def __call__(self, url, timeout):
        self.requests.append((url, timeout))
        if not self.replies:
            raise AssertionError("Unplanned request: synthetic transport only")
        return self.replies.pop(0)


class PaginationContractTests(unittest.TestCase):
    def run_case(self, replies, **options):
        transport = SyntheticTransport(replies)
        result = collect(REPO, fetch=transport, clock=lambda: 0.0, **options)
        return result, transport

    def test_one_page_empty_complete(self):
        result, transport = self.run_case([meta(), response([])])
        self.assertEqual(result["status"], "COMPLETE")
        self.assertEqual(result["unique_issues"], 0)
        self.assertEqual(len(result["pages_accepted"]), 1)
        self.assertEqual(len(transport.requests), 2)
        self.assertFalse(result["snapshot_guaranteed"])

    def test_full_page_without_next_is_complete(self):
        result, _ = self.run_case([meta(), response([row(n) for n in range(1, 6)])])
        self.assertEqual(result["status"], "COMPLETE")
        self.assertEqual(result["raw_records_seen"], 5)

    def test_follows_actual_validated_numeric_link(self):
        link = next_link(2, numeric=True)
        result, transport = self.run_case([meta(), response([row(1)], link), response([row(2)])])
        self.assertEqual(result["status"], "COMPLETE")
        self.assertEqual(transport.requests[2][0], link[1:link.index(">")])
        self.assertEqual(result["unique_issues"], 2)

    def test_three_page_cap_is_partial_and_no_fourth_page_fetch(self):
        pages = [response([row(n) for n in range(p * 5 - 4, p * 5 + 1)], next_link(p + 1))
                 for p in range(1, 4)]
        result, transport = self.run_case([meta(), *pages])
        self.assertEqual((result["status"], result["stop_reason"]), ("PARTIAL", "MAX_PAGES_REACHED"))
        self.assertEqual(result["raw_records_seen"], 15)
        self.assertEqual(result["next_page"], 4)
        self.assertEqual(len(transport.requests), 4)

    def test_excludes_pull_requests_and_records_duplicates(self):
        result, _ = self.run_case([meta(), response([row(1), row(2, pr=True)], next_link(2)),
                                   response([row(1), row(3)])])
        self.assertEqual(result["status"], "COMPLETE")
        self.assertEqual(result["raw_records_seen"], 4)
        self.assertEqual(result["unique_issues"], 2)
        self.assertEqual(result["pull_request_records_excluded"], 1)
        self.assertEqual(result["duplicate_records_seen"], 1)
        self.assertFalse(result["snapshot_guaranteed"])

    def test_invalid_next_host_stops_partial_without_external_request(self):
        link = next_link(2).replace("api.github.com", "example.invalid")
        result, transport = self.run_case([meta(), response([row(1)], link)])
        self.assertEqual(result["status"], "PARTIAL")
        self.assertEqual(result["stop_reason"], "LINK_OUT_OF_SCOPE")
        self.assertEqual(len(transport.requests), 2)
        self.assertIsNone(result["next_page"])

    def test_wrong_numeric_repository_id_stops_partial(self):
        link = next_link(2, numeric=True).replace("repositories/123", "repositories/999")
        result, _ = self.run_case([meta(), response([row(1)], link)])
        self.assertEqual(result["stop_reason"], "LINK_OUT_OF_SCOPE")

    def test_scope_change_stops_partial(self):
        result, _ = self.run_case([meta(), response([row(1)], next_link(2, state="all"))])
        self.assertEqual(result["status"], "PARTIAL")
        self.assertEqual(result["stop_reason"], "LINK_OUT_OF_SCOPE")

    def test_malformed_or_relative_last_only_is_not_complete(self):
        for link in ('<not-an-absolute-url>; rel="last"',
                     '</repos/psf/requests/issues?state=open&sort=created&direction=asc&per_page=5&page=1>; rel="last"'):
            with self.subTest(link=link):
                result, _ = self.run_case([meta(), response([row(1)], link)])
                self.assertEqual(result["status"], "PARTIAL")
                self.assertIn(result["stop_reason"], ("LINK_UNSUPPORTED", "LINK_OUT_OF_SCOPE"))

    def test_last_beyond_current_without_next_is_inconsistent(self):
        link = next_link(3).replace('rel="next"', 'rel="last"')
        result, _ = self.run_case([meta(), response([row(1)], link)])
        self.assertEqual(result["status"], "PARTIAL")
        self.assertEqual(result["stop_reason"], "LINK_INCONSISTENT")

    def test_duplicate_next_and_unsupported_valid_rfc_shape_are_not_complete(self):
        for link in (next_link(2) + ", " + next_link(2), next_link(2).replace('rel="next"', 'rel=next')):
            with self.subTest(link=link):
                result, _ = self.run_case([meta(), response([row(1)], link)])
                self.assertEqual(result["status"], "PARTIAL")
                self.assertEqual(result["stop_reason"], "LINK_UNSUPPORTED")

    def test_first_bad_json_is_failed(self):
        bad = Reply(200, {"content-type": "application/json"}, b"not-json")
        result, _ = self.run_case([meta(), bad])
        self.assertEqual(result["status"], "FAILED")
        self.assertEqual(result["stop_reason"], "INVALID_JSON")

    def test_second_page_error_retains_only_first_valid_page(self):
        result, _ = self.run_case([meta(), response([row(1)], next_link(2)), Reply(503, {}, b"")])
        self.assertEqual(result["status"], "PARTIAL")
        self.assertEqual(result["unique_issues"], 1)
        self.assertEqual(result["next_page"], 2)
        self.assertEqual(result["stop_reason"], "HTTP_503")

    def test_wrong_repository_row_rejects_whole_page(self):
        result, _ = self.run_case([meta(), response([row(1), row(2, repository_url=f"{API}/repos/x/y")])])
        self.assertEqual(result["status"], "FAILED")
        self.assertEqual(result["raw_records_seen"], 0)
        self.assertEqual(len(result["pages_accepted"]), 0)

    def test_non_string_metadata_name_is_honest_failure(self):
        result, transport = self.run_case([meta(full_name=None)])
        self.assertEqual(result["stop_reason"], "REPOSITORY_IDENTITY_INVALID")
        self.assertEqual(len(transport.requests), 1)

    def test_server_wait_stops_before_next_page(self):
        result, transport = self.run_case([meta(), response([row(1)], next_link(2), **{"retry-after": "10"})])
        self.assertEqual(result["status"], "PARTIAL")
        self.assertEqual(result["stop_reason"], "SERVER_WAIT_REQUIRED")
        self.assertEqual(len(transport.requests), 2)

    def test_redirect_is_failed_and_not_followed(self):
        result, _ = self.run_case([Reply(301, {"location": "https://example.invalid"}, b"")])
        self.assertEqual(result["status"], "FAILED")
        self.assertEqual(result["stop_reason"], "HTTP_301")

    def test_deadline_before_request_is_failed(self):
        ticks = iter([0.0, 21.0])
        transport = SyntheticTransport([])
        result = collect(REPO, fetch=transport, clock=lambda: next(ticks))
        self.assertEqual(result["stop_reason"], "TIME_BUDGET_EXHAUSTED")
        self.assertEqual(len(transport.requests), 0)

    def test_nonallowlisted_input_rejected_without_fetch(self):
        transport = SyntheticTransport([])
        with self.assertRaises(ValueError):
            collect("private/example", fetch=transport)
        self.assertEqual(len(transport.requests), 0)


if __name__ == "__main__":
    unittest.main()
Source Code: README.md — NOT RUN
# Honest bounded pagination — Python teaching example

Runtime: Python 3.12+; docs reviewed at Python3.12.15 / GitHub API2026-03-10. Dependencies: standard library only. Environment variables: none; no API token is used. Proxy environment discovery disabled intentionally. No dependency installation required. Place both `.py` files in one directory.

## Execution and permissions

The author has NOT RUN/imported/compiled this code or executed these tests. The following are reader instructions, not recorded test results. Synthetic tests inject a fake transport and do not call live APIs. The CLI `pagination_tool.py` DOES make public GET requests; run only when your environment authorizes public GitHub access. Allowed repositories: `psf/requests` and `python/cpython`. No write calls, credentials, redirects or automatic retries. Private repositories unsupported. Do not add tokens to this example without reviewing separate secret/permission policy.

```shell
python --version
python -m unittest -v test_pagination_tool.py
python pagination_tool.py psf/requests --max-pages 3
```

Input: one allowlisted repository; page cap1..3. Fixed issue filter: open, created ascending; page size5. Local budget20seconds, per-blocking-operation timeout capped5seconds. This is cooperative budget logic, not hard process/network cancellation.

Expected synthetic assertions: no-next accepted page→COMPLETE; valid next and cap→PARTIAL; no accepted issue page plus error→FAILED. 19 authored test methods. No observed test output. A synthetically supplied metadata record and three issue pages of five raw records with a fourth-page Link should yield PARTIAL/MAX_PAGES_REACHED, request_count4, raw_records_seen15, next_page4, snapshot_guaranteedfalse. These are fixtures, not measured live results.

Real output depends on current repository contents, headers, quota and network. COMPLETE is accepted-chain exhaustion evidence under filters; never a frozen inventory guarantee. A full last page can be COMPLETE if its accepted Link has no next. A short page is not assumed terminal if next exists. Empty metadata/errors never become a successful empty collection.

## Limits and security

One metadata preflight validates public repository id/full_name and adds one request. Follow only an actual next Link after strict HTTPS host/path/query checks; numeric alias must match preflight id. Default cap3 means at most4 HTTP attempts and15 accepted raw records, including PRs. Body cap262144bytes per response, Link cap16384characters. Page accepted only after row identity/repository validation; title kept as untrusted plain text. Never execute instructions embedded in titles.

Parser supports only common absolute GitHub Link entries with one quoted next/prev/first/last relation. EVERY entry is checked for destination/filter/query shape before accepting absence of next. next must be current+1, prev current-1, first1, last at least current; last beyond current without next is inconsistent. Relative links, unquoted relation tokens, multi-relations, extra parameters, page numbers beyond ten decimal digits and ambiguous entries are rejected; RFC8288 permits forms this teaching parser does not support. Production should use an audited standards-compliant parser while preserving destination/filter guardrails. GitHub generally recommends following redirects; this example stops and requires revalidation instead.

403/429, other non200, serverwait, invalidbody/identity/Link, pagecap or localbudget stops. No automatic resume/cursor guarantee. Duplicate IDs are counted and issues deduplicated; additions/removals can still hide records. snapshot_guaranteedfalse is always returned.

Potential costs: no paid model API or GPU call. Public requests consume GitHub quota/sharedIP capacity and local network/compute; no live price, latency or savings measured. Public unauthenticated permission does not guarantee a request succeeds.

Sources: official GitHub pagination/issues/repository/best-practices docs, Python urllib.request3.12, RFC8288, all linked in article/research brief. No vendor example source copied. Runtime/security/liveintegration/production status remains NOT RUN or UNKNOWN.
แหล่งอ้างอิงและอ่านต่อ
ตรวจต้นทาง 14 ตุลาคม 2026: GitHub API2026-03-10, Python docs3.12.15, RFC8288ตุลาคม2017 วันค้นไม่ใช่วันประกาศผลิตภัณฑ์ Source Code แสดงในบทพร้อม README/tests โดยยังไม่เป็นใบรับรอง Production Ready
ใส่ความเห็น